Rollback and the failure policy
A new release is pending until it has been healthy for grace + 2×interval. If it goes unhealthy for rollback.on_unhealthy_for before that, the supervisor puts the previous release back from its own layer cache, no network needed, reports it, and the console stops offering that release to that container.
A fleet's On failure setting covers the rest: a release that cannot start at all, or fails after the old app has stopped. Roll back, the default, restores the previous release. Report leaves nothing running with /fleetwide/ready and /fleetwide/live at 503, so an orchestrator recreates the container, which then starts on the previous release.
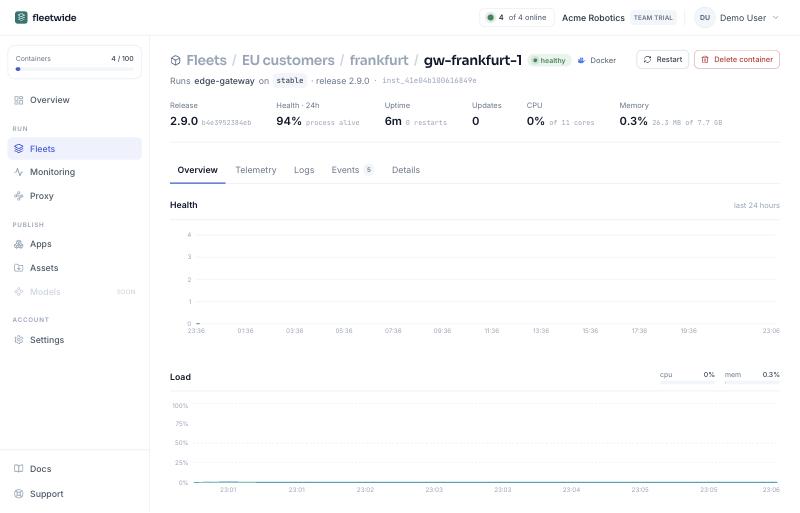
A confirmed release that turns unhealthy later is restarted in place, up to max_restarts, rather than rolled back. The container page keeps the releases it has seen, its events (enrolled, updated, rolled back, restarted, exited with code or signal, out of memory) and its health over the last day.